
LLM Token Allocation
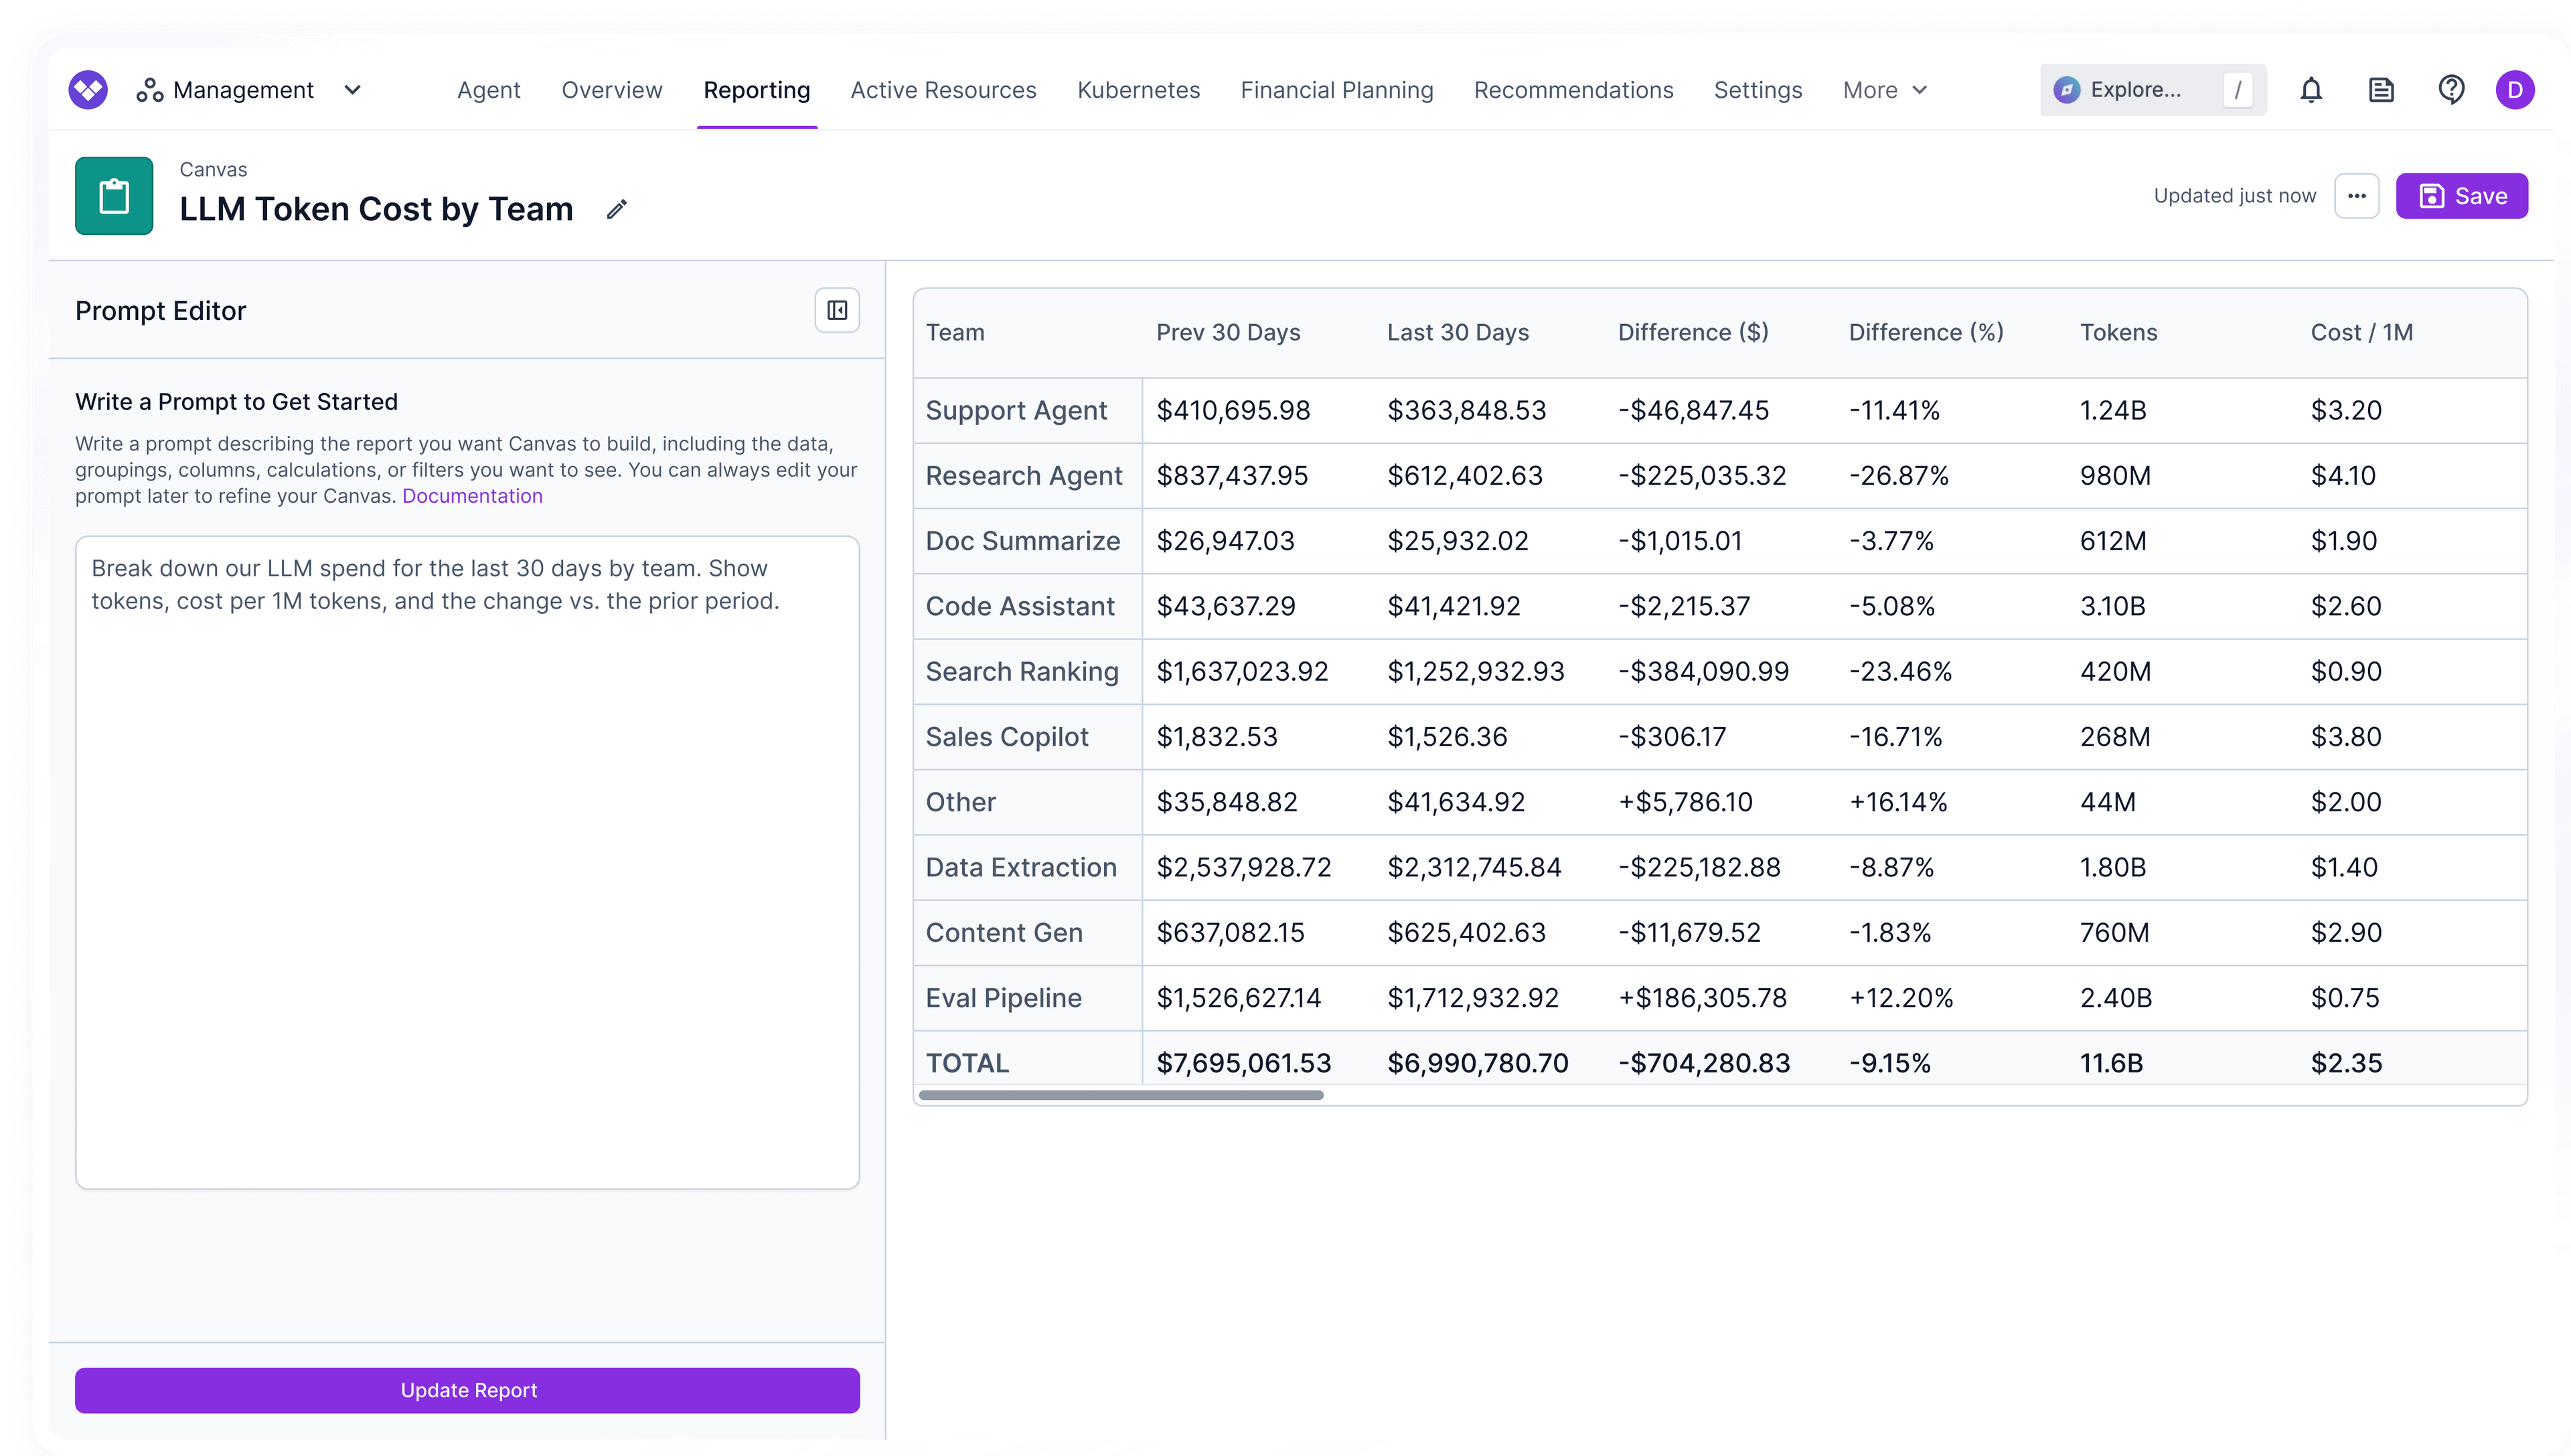
Understand who and what is driving your AI spend. Deliver per-request token telemetry in one provider-agnostic schema, and Vantage attributes every model call back to the teams, customers, and features behind it, whether you call a model API or host the model yourself.


Case study

Adoption of Vantage exceeded our expectations. Engineers genuinely want to see the impact of their optimizations, and Vantage provides them with the tools to do so in real time.
Rami Leshem —VP of Platform Engineering, Extend
Read case studyOne specification for every provider
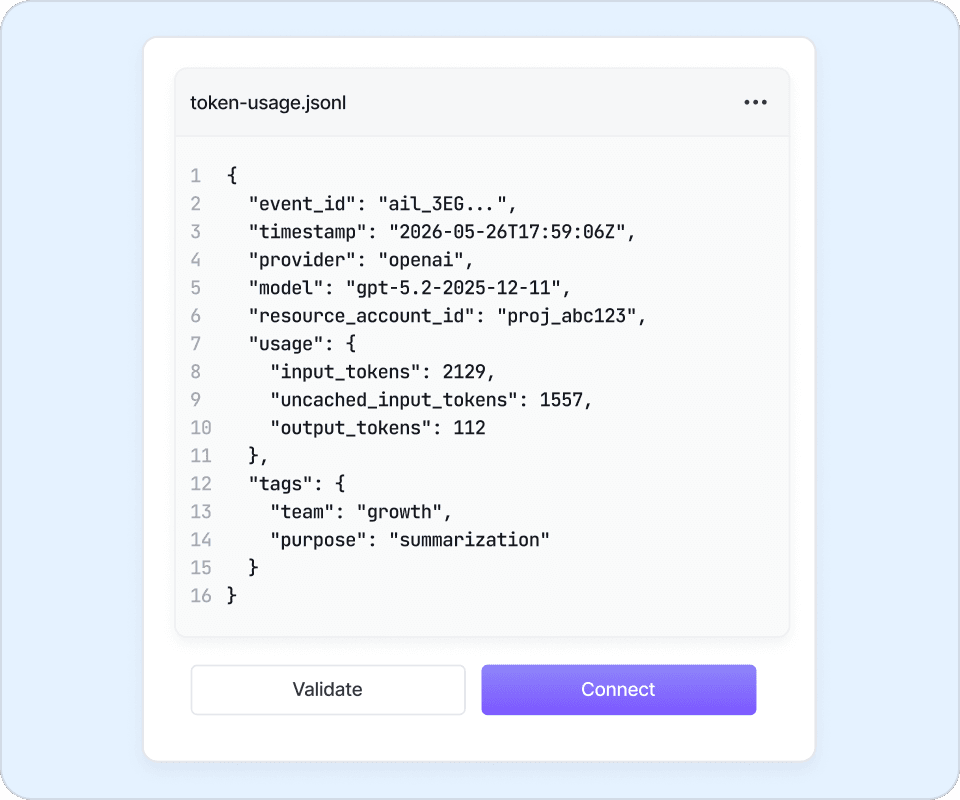
Emit a single JSON record per model request in the Token Cost Allocation Specification, one common schema. Each log carries the provider, model, token counts, and the allocation tags you choose, so a single, consistent allocation model survives a change of provider, gateway, or observability vendor.
Works with any provider, gateway, or none at all
Enrich costs across OpenAI, Anthropic, AWS Bedrock, Google Cloud, and Azure OpenAI today, with native support for LiteLLM, Cloudflare AI Gateway, Bifrost, and AWS Bedrock invocation logs, and native support for OpenRouter coming soon. For anything else, emit the telemetry yourself: it works whether you call providers directly, run your own gateway, or use one Vantage does not yet support.
Allocate every token to a team, customer, or feature
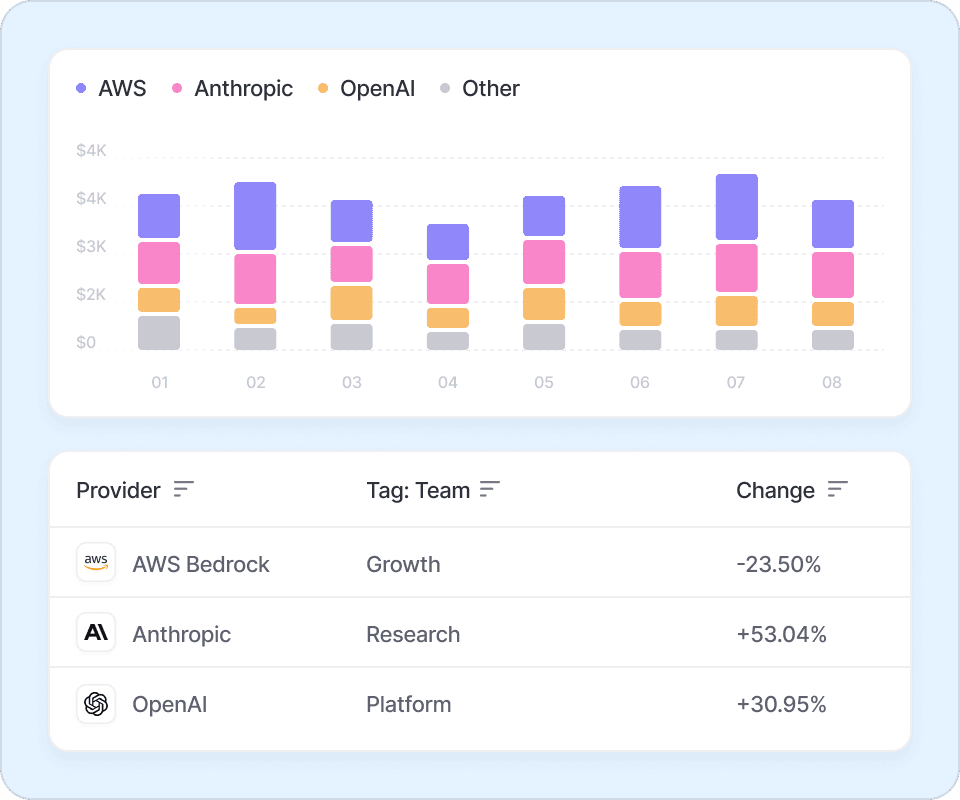
Vantage splits each matching cost row by token share and stamps it with your tags, reconciling back to the provider bill to the cent. Group, filter, forecast, and budget that spend or token usage anywhere tags are supported—Cost Reports, Virtual Tags, Budgets, and Cost Alerts.
Inference Allocation for models you host
Models you host on Modal, Baseten, Together AI, or in your own AWS, Azure, or Google Cloud account are billed for GPU time, not tokens. Inference Allocation groups your request logs by day, model, and provider, matches them to that GPU cost, and splits it with token weights you set, idle time included, across the teams, customers, and features behind the requests.
Read documentation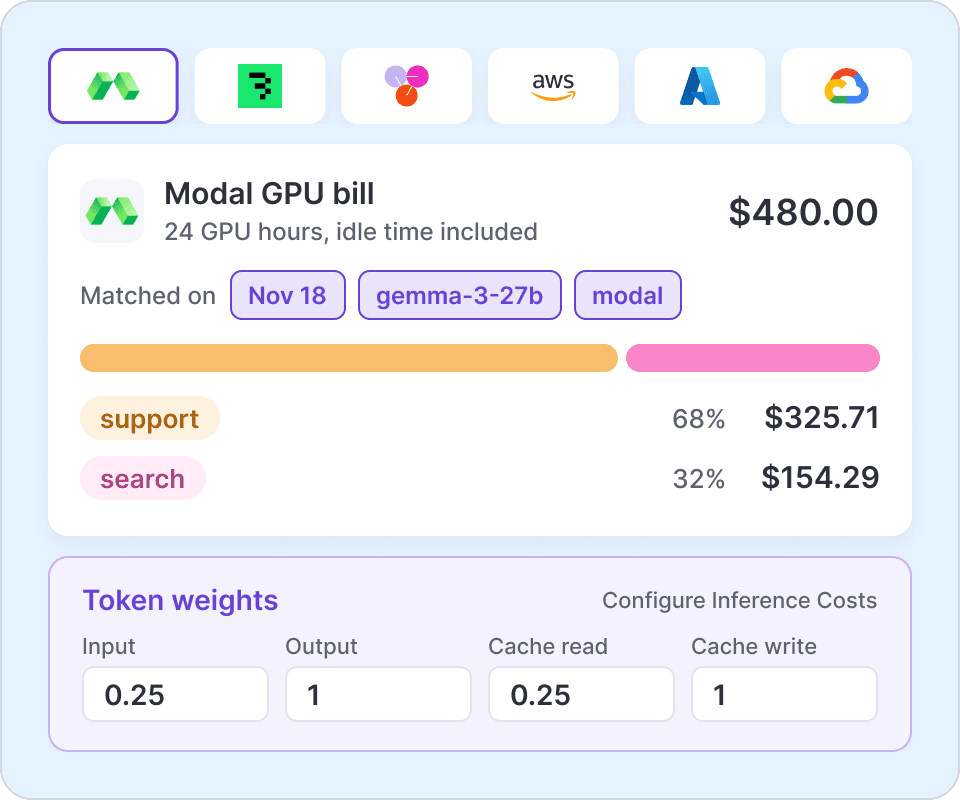
LLM Token Allocation Documentation
Read documentationRead more about delivering token telemetry and allocating LLM costs in the product documentation.